•
Drizz raises $2.7M in seed funding •
•
Featured on Forbes
•
Drizz raises $2.7M in seed funding •
•
Featured on Forbes


Writing test cases used to be a manual craft. A QA engineer read the acceptance criterion, translated it into a test plan, translated test plan into a selector-based script, and then maintained script across every UI refactor for life of feature. Even a mid-sized mobile app with 40 features and a two-week release cycle consumed a full engineer-week per sprint just on test authoring and maintenance. That workflow is now thing being automated away.
A test generation platform takes something a human can describe, an acceptance criterion, a Figma mockup, an API spec, an app URL and produces an executable test that runs against actual product. AWS's engineering guidance on generative-AI test-case creation documents 80% reductions in test-authoring time on internal projects; our own customer runs cluster around 70-90% depending on how mature acceptance-criterion writing already is.
Three input types flow into every real generation platform, and three output types flow out. The interior model doing work is where platforms differ.
Inputs platform reads:
Outputs platform produces:
Not every platform reads all three inputs, and not every platform produces all three outputs. The gap between advertised capability and actual coverage is one of reasons AI generation blogs keep needing to be written.
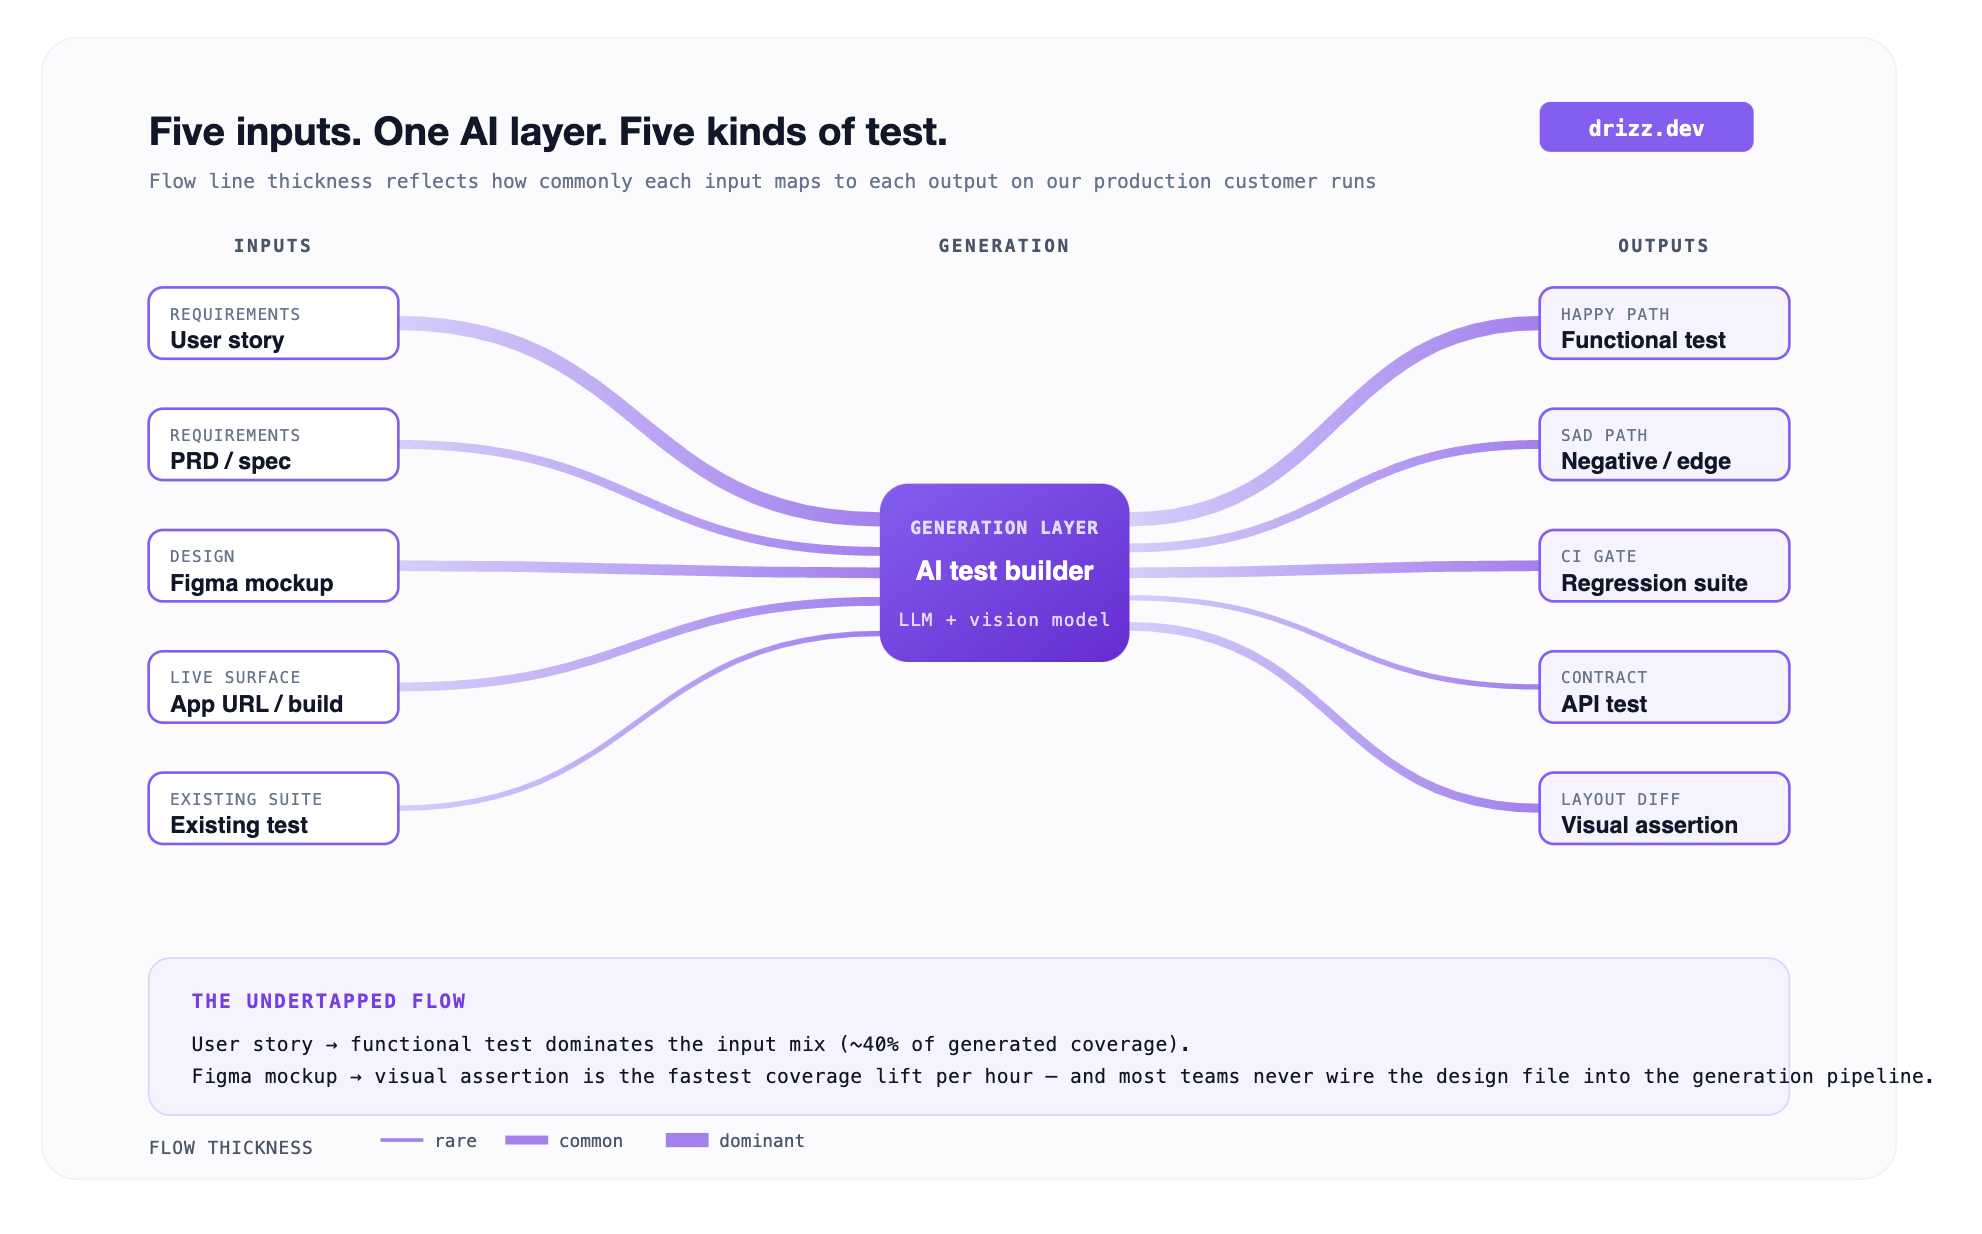
Two observations from our customer data. First: user stories generate most functional coverage because they're input QA teams already write well. Second: Figma-mockup generation is dramatically untapped; most teams have design files sitting in a shared workspace and never feed them to a generation pipeline. Both flows are areas where marginal cost of adding another input is close to zero and coverage lift is real.
Every mature AI-powered generation platform converges on same three-step workflow, and understanding it is what separates teams that adopt technique successfully from teams that abandon it after two sprints.
Direct. A human engineer defines goal in a language platform can understand. For requirements-based generation, this is a well-written acceptance criterion. For mockup-based generation, it's a Figma link with a designated starting frame. For URL-based generation, it's an app build plus a designated entry point. Bad input here produces bad tests "quality of input matters" caveat from AWS's guidance is real, and it's usually where technique fails.
Generate. The platform's LLM (for language reasoning) and vision model (for UI understanding) collaborate to produce a draft test suite. Modern platforms produce this within seconds for a single flow and within minutes for a full feature. The output is not final it's a first draft, deliberately.
Review. A human tester spots logical gaps, catches hallucinated elements (buttons that don't exist, screens platform inferred incorrectly), and approves draft into CI. This is step teams try to skip and shouldn't. Roughly 8-15% of AI-generated tests fail human review on our customer runs; remaining 85-92% ship as production tests with minimal edits.
The core value proposition 80% time reduction, 95% maintenance drop depends on generation step being fast and review step being fast. Platforms that generate tests quickly but produce reviewer-unfriendly output (opaque scripts, no per-step screenshots, no plain-English rationale) fail on review bottleneck instead of generation one.
Four categories of failure show up consistently across every platform we've evaluated. Two are engineering problems tools are getting better at; two are epistemic problems that don't have a purely technical fix.
Four tools cover a meaningful range for AI-powered mobile test generation in 2026. Each handles a distinct subset of input-output matrix above, and each has a specific limit for mobile audience.
We built Drizz because mobile test generation is a layer where incumbents are weakest. Almost every AI test generation platform on market started web-first Selenium/Playwright underneath, DOM-based selectors as ground truth. Porting that architecture to mobile means fighting platform: Appium bridges, per-locale selector maintenance, and OS-version-specific test files. We built vision model as ground truth from day one, which means same generation pipeline works across iOS and Android without a bridge layer.
A Drizz-generated test starts from one of three inputs and produces plain-English steps that run on a real iOS or Android device:
Input: acceptance criterion
"As a user, I can log in with email and password and see my dashboard"

Generated test:
Tap the Login button
Type "test@example.com" in the Email field
Type "password123" in the Password field
Tap Sign In
Verify the home screen shows "Welcome back"
Four things we do that no other tool on this list does end-to-end for mobile:
The technique underneath is what we call Vision AI mobile testing architecture that makes mobile generation viable without per-platform, per-locale, per-OS maintenance overhead.
Best for: any mobile team where acceptance criteria are primary artifact QA works from, and where review budget is constraint (not authoring one).
testRigor generates tests from plain-English descriptions and is closest cross-surface competitor on authoring layer. A testRigor test reads like English and covers web, mobile, and API from a single syntax. Widely reviewed on G2 as category leader for natural-language test authoring.
The specific limit for mobile generation: testRigor is selector-driven under hood with AI interpretation on top. When engineering refactors mobile view hierarchy (which happens more often than DOM refactors on web), AI interpretation starts guessing at nearby elements, and generated tests that used to pass start returning false positives. On mobile specifically, platform requires a bridge to Appium or a native SDK integration for full generation coverage, which reintroduces per-platform maintenance overhead their web offering avoids.
Best for: teams where PMs or QA analysts need cross-surface generation (web + mobile + API from one syntax) and where engineering handles underlying locator layer.
Mabl generates tests from a mix of visual authoring and AI-assisted maintenance. Strong CI/CD integration, mature analytics layer (flakiness, coverage, regression tracking), and a good story for web regression at scale.
The specific limit for mobile generation: Mabl's mobile support is smaller and newer than its web offering. Test generation from Figma mockups is not natively supported; workflow starts from a live app running on Mabl's cloud, which means you're already past design phase before generation begins. The tool is also built for a QA analyst persona with fixtures, data-driven configs, and test-case management concepts that PMs and designers typically don't carry.
Best for: teams with a QA analyst dedicated to test-suite ownership, primarily on web stacks where mobile is a supplemental surface and where analytics on test quality matter more than input flexibility.
Functionize is enterprise-focused with a strong NLP layer and deep integration hooks for Jira and Azure DevOps. Test generation happens from natural-language requirements, and platform is one of earlier movers in AI test generation category.
The specific limit for mobile generation: Functionize is predominantly web-focused, with mobile as a secondary surface. Generation from Figma mockups and generation from mobile APK/IPA builds are both areas where tool trails specialized mobile-first platforms. The enterprise-heavy pricing and setup model also mean platform is a poor fit for teams under 200 engineers, where setup ROI hasn't been earned yet.
Best for: large enterprises with dedicated QA orgs, existing DevOps tooling investments (Jira + Azure DevOps), and mostly-web test coverage where mobile is a supplemental layer.
The broader tool-selection framework for AI testing category sits in our mobile testing tool evaluation, which covers trade-offs across code-first vs. no-code, cloud vs. self-hosted, and mobile-first vs. web-first architectures.
AI-powered generation is an authoring layer of QA stack. It removes manual transcription costs between acceptance criteria and running test. Four categories stay outside its scope even when generation pipeline is working well:
Our take: AI test generation removes 70-80% of mechanical authoring cost and leaves judgment-heavy 20-30% where it belongs with humans who understand product.
Natural language authoring lets a human write a test in English; platform interprets and runs it. AI test generation goes one step further: the platform produces test itself from an upstream artifact (acceptance criterion, Figma, or URL). Generation is a superset that includes authoring. Our natural-language mobile test automation covers authoring layer specifically.
Yes, and they should be. The generation platform produces a draft; human reviewer edits it. On Drizz, edits happen in same plain-English format test was generated in no context switch to a scripting language. Roughly 12% of generated tests need edits on our customer runs, most of them to add assertions model didn't infer from input.
For features with well-written acceptance criteria, roughly 80% of initial test suite can be AI-generated. The other 20% covers business-rule edge cases, cross-service integrations, and unusual state scenarios that input didn't describe. Over time, as generation platforms get better at inferring context, 80% number rises, but the 20% that requires human judgement is not going to zero.
Historically no most platforms started web-first, and their mobile stories are recent additions layered on top. That's a specific gap we built Drizz to close. The vision-model architecture works identically across iOS, Android, native, React Native, and Flutter because it reads rendered screen rather than platform-specific element tree.
Generation happens once per new feature, ideally at design-doc-ready or acceptance-criterion-approved time. Execution happens on every commit, PR, or release candidate depending on suite's runtime budget. The generation step is offline; execution step is online. Our no-code mobile test automation covers where generated suites sit alongside handwritten suites in a mature pipeline.




©Drizz 2026 • All Rights Reserved






