•
Drizz raises $2.7M in seed funding •
•
Featured on Forbes
•
Drizz raises $2.7M in seed funding •
•
Featured on Forbes


A payment startup we work with ran a regression pass and every payment-flow test failed at same step. The issue wasn't in app. Someone on QA team had rotated test Stripe keys previous night without notifying automation suite, and every test that ran against payment sandbox got a "test card declined" response. The suite ran green for eleven months before this happened. The failure surfaced within a single sprint of rotation.
That's a test data problem, and it's shape of every serious mobile QA operation eventually. Real test suites don't fail because code broke; they fail because data broke a stale sandbox key, an expired test user, a synthetic phone number that a new SMS provider now blocks, a country code payment gateway no longer accepts. Getting test data right is what separates a QA suite that runs green for a year from one that turns red every sprint for reasons unrelated to product.
Test data is set of user accounts, inputs, and app states that automated and manual tests operate against. A test that "logs in with valid credentials and reaches dashboard" needs a real credential pair to submit; a test that "adds a $10 item to cart and checks out" needs a real payment method sandbox accepts. Without test data, no test runs.
Mobile test data has one property that web test data doesn't. Native mobile flows cross real device boundaries SMS delivery, biometric authentication, native payment sheets (Apple Pay, Google Pay), push notifications. The data feeding those flows has to work end-to-end through real infrastructure, not just through a browser API mock. That's why mobile test data problem is harder than it looks: data isn't just strings and numbers, it's whole chain that mobile OS invokes when a test runs.
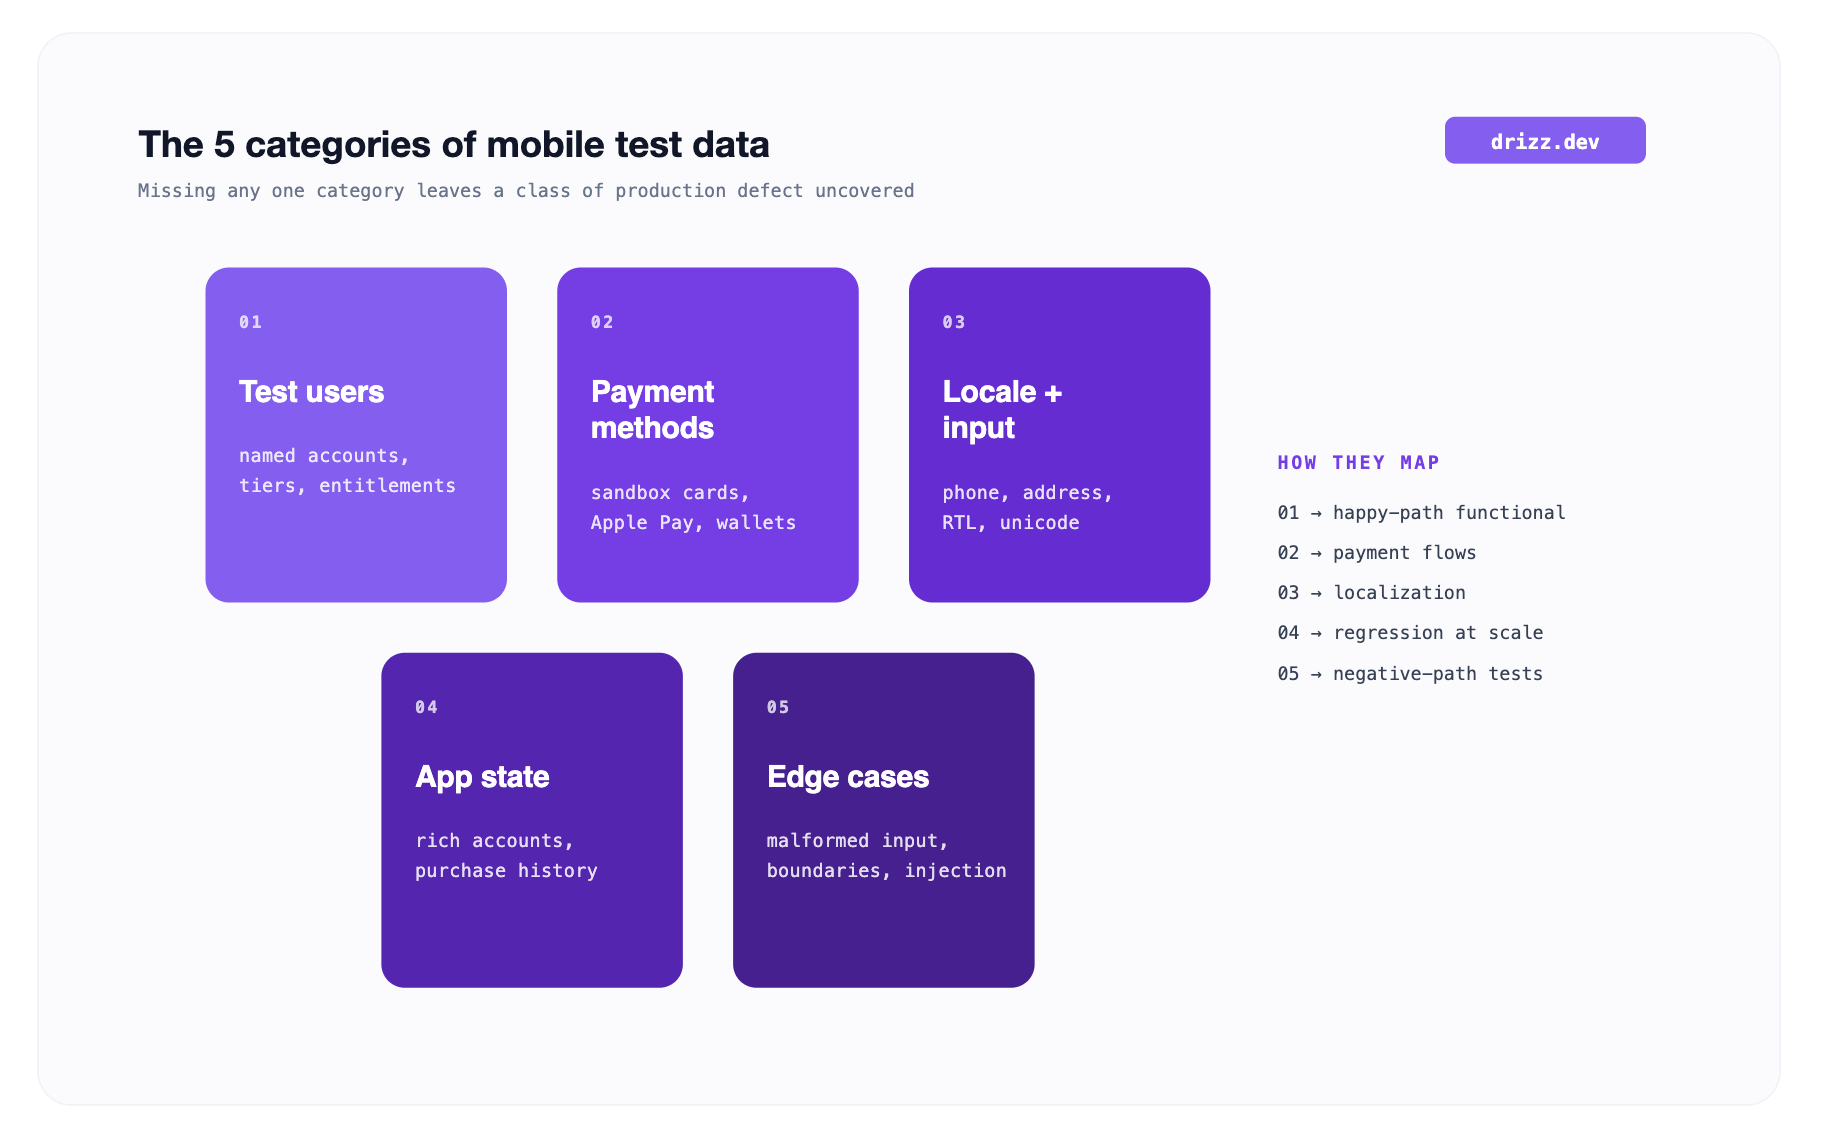
Every mature mobile QA suite carries data across five categories. Missing any one category leaves a class of production defects uncovered.
1. Test users. Named accounts with known credentials, entitlement tiers, and pre-loaded state. A commerce app needs at least one free-tier user, one premium user, one blocked user, one user with a full loyalty balance, and one brand-new empty user. Each covers a different code path. Manual creation works for first three; automated user provisioning (via API or a fixture reset script) is only sustainable approach past that.
2. Test payment methods. Sandbox cards for Stripe, Adyen, PayPal, Braintree, Razorpay, and each regional gateway app supports. Real card numbers with known outcomes 4242 4242 4242 4242 triggers success, 4000 0000 0000 0002 triggers a decline, 4000 0000 0000 9995 triggers insufficient funds. The Stripe test card list is reference for what codes exist. Mobile flows also need Apple Pay / Google Pay sandbox setups, which live outside card gateway's own docs.
3. Test locale and input data. Phone numbers per country (with valid formats and known SMS-delivery behavior), postal codes per region, addresses that pass validation in each market, localized name inputs (Cyrillic, CJK, Arabic RTL), currency amounts formatted per locale. A single "test checkout" flow multiplies into 5-10 country-specific variants once localization coverage kicks in.
4. Test app state. Pre-loaded scenarios that let tests skip past onboarding. A user with a 2-year purchase history, a user with a partially filled shopping cart, a user with a saved shipping address, and a user with 47 conversations in inbox. Teams that test only from an empty state miss an entire class of defects that surface with realistic data volumes.
5. Edge-case and negative-path data. Malformed inputs, boundary values, Unicode edge cases, extremely long strings, SQL injection patterns, and XSS payloads. This is data that verifies error handling. '', NULL, a 4,000-character name, an emoji in a phone number field every field needs at least one deliberately broken input in the regression suite.
Four sources, each with a distinct trade-off between fidelity, safety, and setup cost.
The right combination usually looks like synthetic data for functional and negative-path tests, masked production copies for realistic-load and regression suites, and manual entry for a small set of "known named" accounts that never change.
Three regulatory frameworks show up on almost every mobile QA compliance conversation. The specific obligations depend on where your users live and what data you handle, but shape is consistent.
For most mobile teams, the compliance floor is no production PII in staging without an active masking pipeline and no real payment cards in any non-production environment ever.
Test data drifts. Users get suspended, cards expire, phone numbers get recycled, and addresses become invalid. A test suite that ran green in January will start failing in June for reasons unrelated to code data underneath being aged. Mature teams manage this with three practices.
Our broader test data management for mobile apps guide covers strategy layer above these tactics.
Test data tools split into two camps for mobile teams. Generators produce synthetic data on demand for functional tests. Managers provision, mask, and refresh test data at scale across environments. Most teams start with a generator and add a manager as they grow into compliance requirements.
Drizz is an execution layer, not test data layer. We don't generate synthetic users, mask production copies, or manage payment sandbox credentials. What we do is use test data you've provided to run mobile tests on real iOS and Android devices in plain English.
The typical pairing looks like this. A team provisions test users and test payment cards in Faker + Stripe's sandbox. The test users' credentials get injected into Drizz test steps via variables. Drizz runs tests on real devices, catching every visual regression and interaction bug vision model spots, and reports pass-fail back to TestRail / Zephyr / Qase. The test data pipeline and test execution pipeline are separate concerns handled by different tools.
If your team is stuck running mobile tests with fragile locators against unstable test users two most common causes of flakiness Vision AI mobile testing architecture removes locator half of that problem. The test data half stays with your TDM layer.
Enough to cover every user tier, every payment method, every locale you ship, and at least one representative "rich-state" account per feature area. For a mid-sized commerce app: roughly 20-30 named test users, 15-20 sandbox payment methods across 3-5 gateways, and one rich-state fixture per feature. Automated suites re-use these across thousands of test runs.
Legally yes if consent is specific and revocable. Practically almost never does the operational overhead of tracking consent, honoring withdrawal, and isolating consented data outweigh fidelity benefit. Every serious mobile QA operation uses masked-production or fully synthetic data, not consented real data.
Real devices with test SIM cards and a service like Twilio's test credentials or an SMS-testing service like SafetyTest that returns predictable codes on demand. Emulators can't test real SMS delivery. Android's SMS Retriever API doesn't fire correctly on emulators. Our broader Vision AI mobile testing coverage explains why real devices matter for verification flows.
Roughly one full engineer-day per sprint is spent on false-positive investigations, plus real production defects that ship because a coverage gap wasn't caught. Teams that mature their test data practice typically recover 15-20% of QA capacity within a quarter.
No, until you're not. Faker + Stripe sandbox + a manual list of 20 named test users runs fine at 1-30 engineers. Past 30-50 engineers, or first regulated-industry contract, a proper TDM platform becomes worth its cost. Our broader mobile testing tool evaluation guide covers full evaluation framework for adjacent categories.




©Drizz 2026 • All Rights Reserved






