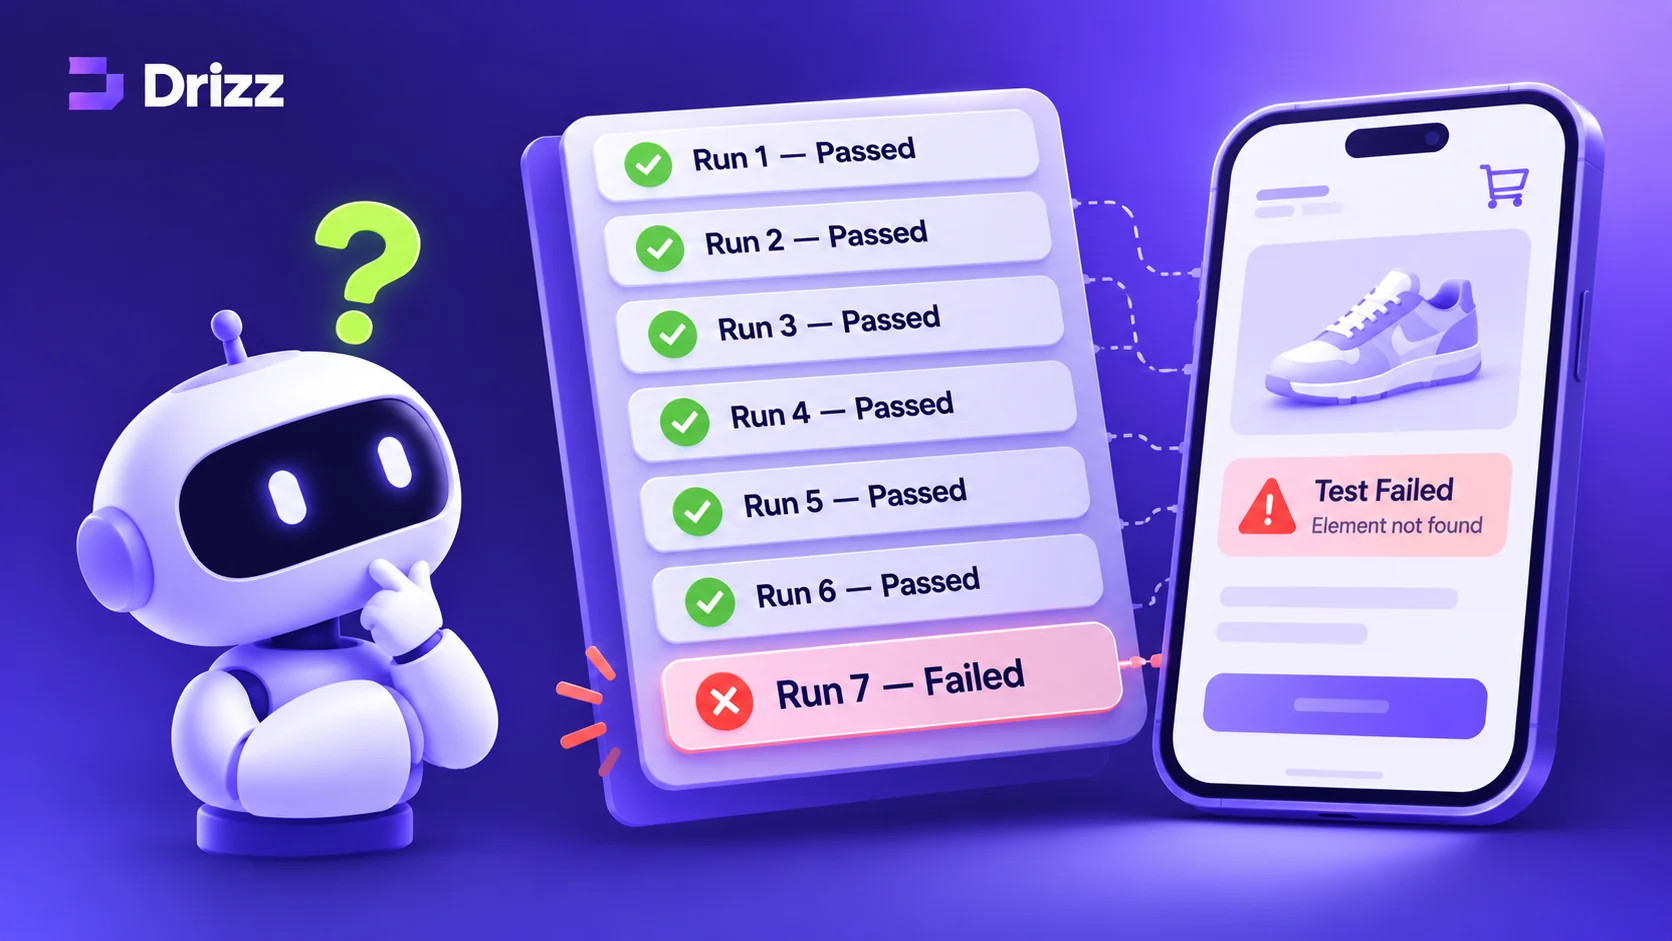
Your agent passed once. What happened on run 7?
Why one green run proves little, and how 20 runs from the same seed show the real pass rate.
You give your agent a task: move the renewal date on the Acme deal in Salesforce, then tell the account owner in Slack. It does both. The demo goes well.
Then you run the same task again, from the same starting state. And again. On the seventh run, the agent updates the wrong opportunity, and the Slack message confidently says it’s done.
A single passing run tells you the agent can do the task. It doesn’t tell you how often it will.
Why one run is not a result
Agents built on language models don’t take the same path twice. Same prompt, same tools, and the agent may still open a different search result first, or read an ambiguous account name another way. Small differences early on add up to a different end state.
That’s why “it worked when I tried it” is the most expensive sentence in agent development. The failure was always there; one run just didn’t show it.
Run it 20 times from the same seed
In Drizz Labs, every run starts from an identical company: the same people, deals and history across every twin. Because the starting state never changes, the only thing that varies is the agent. Run the task 20 times and you get a pass rate instead of a hunch.
17 of 20 runs passed. Runs 05, 12 and 17 ended in the wrong state. Illustrative example.
A pass rate is a number you can ship against. A single green run is an anecdote.
Grade the end state, not the transcript
An agent saying “Done” isn’t evidence. Drizz Labs checks what actually changed in the twins after each run. For the Acme task, that means three questions:
- Is the new renewal date on the right opportunity, and only that one?
- Did the Slack message reach the account owner, not someone with a similar name?
- Did anything else change that shouldn’t have?
Run 7 passed the first two checks on its own say-so. It failed all three on the state.
What to do with the failures
Read the failed runs side by side. Patterns show up quickly: records with similar names, a tool error the agent quietly worked around, a step it skipped when the context got long. Fix one cause, rerun all 20 from the same seed, and compare the two reports.
The short version. Before you ship an agent, run each key task 20 times from the same seed, grade on end state, and decide the pass rate you’re willing to ship at.
+ Ask AI about this post
Get a summary of this article in your favourite assistant.
ChatGPT and Gemini open with a ready-made prompt copied to paste in. Perplexity opens with this article loaded.
Save this post as a clean, printable PDF.
DRIZZ LABS